The Crawl Balance Sheet: Pricing Bot Access Before the UK Retail Peak in 2026
Photo: UK retail server room analytics dashboard peak season bot traffic, via i.pinimg.com
By mid-November 2026, UK retail teams are finalising stock files, paid media plans and delivery cut-offs. Behind those visible preparations, another queue is forming at the origin: search crawlers, AI answer engines, shopping agents and training bots all requesting the same product, category and stock pages. Capacity is finite. The useful question is not whether to allow or block bots in general, but how much capacity each class should receive, at what priority, and what commercial exposure that allocation creates.
Begin with a verified bot ledger
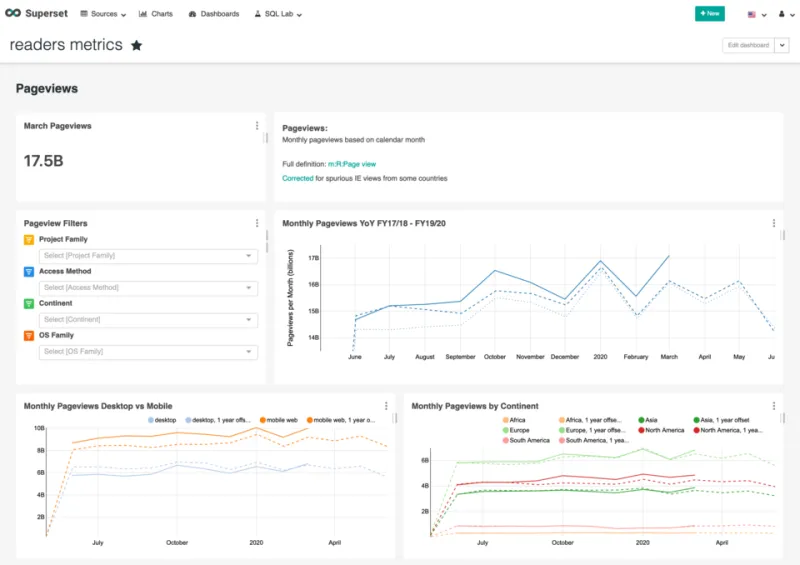
A blocklist is not a budget. Start with a ledger. Group traffic by purpose rather than by user-agent string: search crawlers that support indexing, AI answer engines that may cite or summarise pages, shopping agents that check price and availability, training bots that collect content for model development, and unverified scrapers that claim to be any of the above. Verification matters. Reverse DNS, published IP ranges and edge-level bot management should confirm identity before a request is given priority.
The ledger should record, for each verified class, the pages requested, peak requests per second, cache hit ratio, error rate, and any observable downstream signal such as referral sessions, feed errors or stock-query volume. User-agent alone is insufficient because it is trivially spoofed. A retailer does not need perfect attribution to make better decisions; it needs a defensible view of which bot classes are doing commercially useful work and which are simply consuming origin capacity.
Convert requests into revenue exposure
Hit counts are a poor proxy for importance. A category page that is five minutes stale is a merchandising irritation; a stock indicator that is a day stale is a returns problem. Map bot classes to page templates and then to revenue exposure. Product detail pages, stock indicators, promotion pages, delivery-promise messaging and store availability all carry different tolerances for delay.
A simple exposure score can be built from the template share of revenue, the peak traffic multiplier, the sensitivity of that template to staleness, and the degree to which a bot class depends on it. The output does not need to be a false-precision number. It needs to separate the bot traffic that protects revenue from the bot traffic that merely adds load. Shopping agents, for example, are highly sensitive to price and availability. If they cannot read structured data and stock state cleanly, demand may route to retailers with clearer signals. That is not a crawl-statistic issue; it is a lost-sale issue.
Set rate limits at the edge, not in policy documents
Policy documents do not enforce themselves. The practical controls sit in the CDN, WAF or bot-management layer. Verified search crawlers can usually be given generous but bounded rates, with priority for pages that need fresh indexing. AI answer engines may warrant moderate access to editorial and product content, particularly where citation or referral value is measurable. Shopping agents need reliable access to product, price and stock endpoints, but those endpoints should be cached aggressively and separated from checkout or account paths. Training bots can be deprioritised, rate-limited or scheduled outside peak windows where policy allows.
Caching is the cheapest form of crawl budget. Use short time-to-live values for product pages where price and stock change quickly, longer values for stable category copy, and stale-while-revalidate so that bots receive a fast response while the origin refreshes in the background. Exclude cart, account and personalised endpoints from bot caching entirely. For UK retailers, the peak calendar adds urgency: Black Friday falls on 27 November 2026, followed by Cyber Monday and the Christmas delivery cut-off. A rate limit that is comfortable in October can become a commercial constraint in the final week of November.
Test changes as commercial experiments
Do not make blanket changes during peak. Establish a seven-day baseline, then test one variable at a time in a canary group: a percentage of bot traffic, a specific template, or a single bot class. Measure origin latency at the 95th percentile, 5xx rates, cache hit ratio, crawl requests by class, indexed or eligible page counts, AI referral sessions, shopping feed errors and conversion where the link can be observed.
A safe sequence is shadow mode first, then a small canary for 48 to 72 hours, then wider rollout only if error rates remain stable and revenue-linked signals do not deteriorate. Keep rollback immediate. The point is not to prove that a technical change works in isolation; it is to show that it improves or protects commercial outcomes without shifting risk to another part of the stack.
Report the trade-offs in a crawl P&L
Commercial stakeholders do not need a lecture on user-agents. They need a one-page crawl profit-and-loss view: bot class, capacity share, purpose, revenue dependency, control applied, residual risk and owner. Explain decisions in merchant language. For example: we are reserving origin capacity for verified shopping agents on product endpoints because stock accuracy reduces wasted paid clicks and returns. We are delaying training-bot access during peak because it does not support availability, price parity or delivery promises.
That framing turns crawl capacity into a budget rather than a systems argument. It also makes trade-offs visible. If a retailer chooses to block AI answer engines to protect origin capacity, the report should state what visibility or referral exposure may be forgone. If it chooses to allow them, the report should state the capacity cost and the monitoring plan.
In 2026, UK retail search performance depends on how well teams allocate finite origin capacity across competing machine audiences. The crawl balance sheet will not eliminate peak pressure, but it will make the decisions calmer, testable and commercially accountable.